str自始可用
A sequence of Unicode codepoints.
You can iterate over the grapheme clusters of the string using a for loop. Grapheme clusters are basically characters but keep together things that belong together, e.g. multiple codepoints that together form a flag emoji. Strings can be added with the + operator, joined together and multiplied with integers.
Typst provides utility methods for string manipulation. Many of these methods (e.g., split, trim and replace) operate on patterns: A pattern can be either a string or a regular expression. This makes the methods quite versatile.
All lengths and indices are expressed in terms of UTF-8 bytes. Indices are zero-based and negative indices wrap around to the end of the string.
You can convert a value to a string with the str constructor.
Example
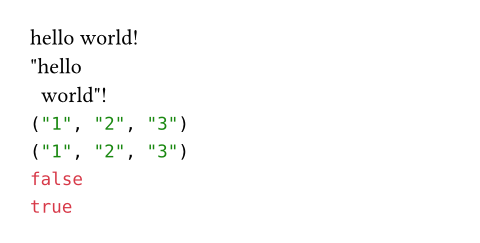
#"hello world!" \
#"\"hello\n world\"!" \
#"1 2 3".split() \
#"1,2;3".split(regex("[,;]")) \
#(regex("\\d+") in "ten euros") \
#(regex("\\d+") in "10 euros")
Escape sequences
Just like in markup, you can escape a few symbols in strings:
\\for a backslash\"for a quote\nfor a newline\rfor a carriage return\tfor a tab\u{1f600}for a hexadecimal Unicode escape sequence
构造函数自始可用
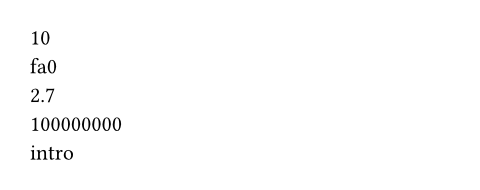
Converts a value to a string.
- Integers are formatted in base 10. This can be overridden with the optional
baseparameter. - Floats are formatted in base 10 and never in exponential notation.
- Negative integers and floats are formatted with the Unicode minus sign (“−” U+2212) instead of the ASCII minus sign (“-” U+002D).
- From labels the name is extracted.
- Bytes are decoded as UTF-8.
If you wish to convert from and to Unicode code points, see the to-unicode and from-unicode functions.
 展开示例
#str(10) \
#str(4000, base: 16) \
#str(2.7) \
#str(1e8) \
#str(<intro>)
value
The value that should be converted to a string.
base默认值:10
The base (radix) to display integers in, between 2 and 36.
定义
len自始可用
The length of the string in UTF-8 encoded bytes.
first自始可用
Extracts the first grapheme cluster of the string.
Returns the provided default value if the string is empty or fails with an error if no default value was specified.
default
A default value to return if the string is empty.
last自始可用
Extracts the last grapheme cluster of the string.
Returns the provided default value if the string is empty or fails with an error if no default value was specified.
default
A default value to return if the string is empty.
at自始可用
Extracts the first grapheme cluster after the specified index. Returns the default value if the index is out of bounds or fails with an error if no default value was specified.
index
The byte index. If negative, indexes from the back.
defaultany
A default value to return if the index is out of bounds.
slice自始可用
Extracts a substring of the string. Fails with an error if the start or end index is out of bounds.
start
The start byte index (inclusive). If negative, indexes from the back.
end默认值:none
The end byte index (exclusive). If omitted, the whole slice until the end of the string is extracted. If negative, indexes from the back.
count
The number of bytes to extract. This is equivalent to passing start + count as the end position. Mutually exclusive with end.
clusters自始可用
Returns the grapheme clusters of the string as an array of substrings.
codepoints自始可用
Returns the Unicode codepoints of the string as an array of substrings.
to-unicode0.5.0起可用
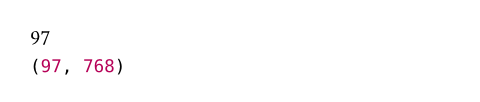
Converts a character into its corresponding code point.
展开示例
#"a".to-unicode() \
#("a\u{0300}"
.codepoints()
.map(str.to-unicode))
character
The character that should be converted.
from-unicode0.5.0起可用
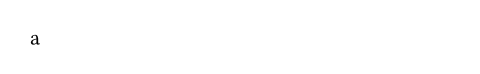
Converts a unicode code point into its corresponding string.
展开示例
#str.from-unicode(97)
value
The code point that should be converted.
normalize0.14.0起可用
Normalizes the string to the given Unicode normal form.
This is useful when manipulating strings containing Unicode combining characters.
#assert.eq("é".normalize(form: "nfd"), "e\u{0301}")
#assert.eq("ſ́".normalize(form: "nfkc"), "ś")form默认值:"nfc"
| Variant | Details |
|---|---|
"nfc" | Canonical composition where e.g. accented letters are turned into a single Unicode codepoint. |
"nfd" | Canonical decomposition where e.g. accented letters are split into a separate base and diacritic. |
"nfkc" | Like NFC, but using the Unicode compatibility decompositions. |
"nfkd" | Like NFD, but using the Unicode compatibility decompositions. |
contains自始可用
Whether the string contains the specified pattern.
This method also has dedicated syntax: You can write "bc" in "abcd" instead of "abcd".contains("bc").
pattern
The pattern to search for.
starts-with自始可用
Whether the string starts with the specified pattern.
pattern
The pattern the string might start with.
ends-with自始可用
Whether the string ends with the specified pattern.
pattern
The pattern the string might end with.
find自始可用
Searches for the specified pattern in the string and returns the first match as a string or none if there is no match.
pattern
The pattern to search for.
position自始可用
Searches for the specified pattern in the string and returns the index of the first match as an integer or none if there is no match.
pattern
The pattern to search for.
match自始可用
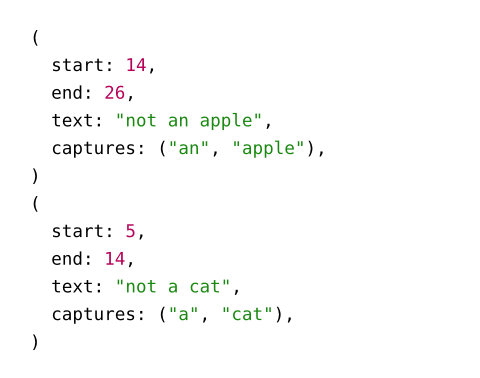
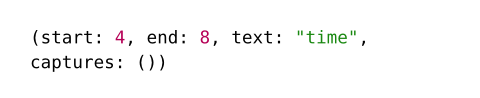
Searches for the specified pattern in the string and returns a dictionary with details about the first match or none if there is no match.
The returned dictionary has the following keys:
start: The start offset of the matchend: The end offset of the matchtext: The text that matched.captures: An array containing a string for each matched capturing group. The first item of the array contains the first matched capturing, not the whole match! This is empty unless thepatternwas a regex with capturing groups.
展开示例:Shape of the returned dictionary
#let pat = regex("not (a|an) (apple|cat)")
#"I'm a doctor, not an apple.".match(pat) \
#"I am not a cat!".match(pat)
展开示例:Different kinds of patterns
#assert.eq("Is there a".match("for this?"), none)
#"The time of my life.".match(regex("[mit]+e"))
pattern
The pattern to search for.
matches自始可用
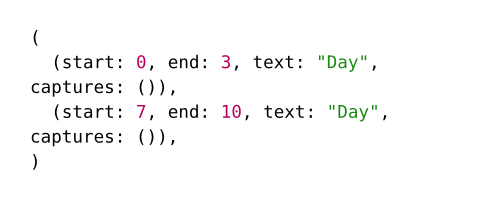
Searches for the specified pattern in the string and returns an array of dictionaries with details about all matches. For details about the returned dictionaries, see above.
展开示例
#"Day by Day.".matches("Day")
pattern
The pattern to search for.
replace自始可用
Replace at most count occurrences of the given pattern with a replacement string or function (beginning from the start). If no count is given, all occurrences are replaced.
pattern
The pattern to search for.
replacement
The string to replace the matches with or a function that gets a dictionary for each match and can return individual replacement strings.
The dictionary passed to the function has the same shape as the dictionary returned by match.
count
If given, only the first count matches of the pattern are replaced.
trim自始可用
Removes matches of a pattern from one or both sides of the string, once or repeatedly and returns the resulting string.
pattern默认值:none
The pattern to search for. If none, trims white spaces.
at
Can be start or end to only trim the start or end of the string. If omitted, both sides are trimmed.
repeat默认值:true
Whether to repeatedly removes matches of the pattern or just once. Defaults to true.
split自始可用
Splits a string at matches of a specified pattern and returns an array of the resulting parts.
When the empty string is used as a separator, it separates every character (i.e., Unicode code point) in the string, along with the beginning and end of the string. In practice, this means that the resulting list of parts will contain the empty string at the start and end of the list.
pattern默认值:none
The pattern to split at. Defaults to whitespace.
rev0.8.0起可用
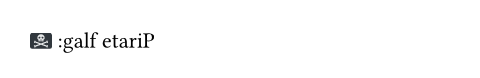
Reverses the string.
More specifically, this returns a string with the same grapheme clusters, in reversed order.
展开示例
#"Pirate flag: 🏴☠️".rev()